Monitoring proxy-backed jobs without logging customer payloads
Monitor proxy-backed jobs with useful metrics and scoped identifiers while keeping customer payloads and credentials out of logs.
Decide what the on-call engineer needs to know
A regional release check can often be diagnosed using a fixture identifier, requested market, observed status, elapsed time and an expected-version flag. Saving the full response or a customer's session token rarely helps answer those first questions. Define a compact event format around the decision the operator needs to make when a job fails.
Use identifiers with bounded scope
Create synthetic run IDs that let internal teams match their own logs without exposing a customer record. Aggregate error classes by product, market and time window. Avoid stuffing full URLs, raw response text or unbounded identifiers into metric labels. Large or sensitive labels can make dashboards costly to operate and difficult to share outside the engineering team.
For a daily summary, a table of completed checks, late checks and wrong-region checks by market can be sufficient. Access to the underlying test job can remain limited to the people who investigate individual issues. OWASP logging guidance.
Make retention a conscious choice
Keep detailed diagnostic events for the period justified by the support process. Review access to logs and document how the team removes data that exceeds its purpose. When evaluating XtremeProxy, ask which usage and connection records the selected plan provides and how long they remain accessible. Combine that information with your own telemetry so an incident report can explain the failure while preserving the privacy of the people using the application.
Enough telemetry to diagnose a missing report
A team needs to distinguish a timeout from a stale response and a validation failure. Its synthetic monitor can emit a bounded route label, stage, duration, status class and opaque run identifier. Count failures by stage and correlate one affected run with the authorized application log. A full HTML response or URL with customer query parameters is unnecessary. Limit label cardinality so customer identifiers cannot quietly become metric dimensions or drive uncontrolled storage costs.
Design metrics with bounded labels
Market codes and defined error classes can make useful aggregate dimensions. Full request URLs, personal identifiers and arbitrary response text can create sensitive or unbounded labels. Use a short-lived controlled correlation reference when an authorized investigator needs to connect two events. Test the logging format with deliberately synthetic input.
A URL can contain private customer data in its path and query, even when the response body is never logged. On an owned fixture, substitute a route template and an internal operation label before emitting metrics. Check a sample of the actual exported telemetry after the transformation.
Make the failure stages countable
A daily synthetic report observes 100 checks, including two timeouts, one wrong revision and one authorized window missed by the scheduler. Those exceptions need different owners. Fixed stage labels allow an operator to group them without reading payloads. Check that successes, classified failures and unobserved opportunities reconcile to the scheduled count.
Choose retention separately for detailed sample traces and monthly reliability totals. A short-lived trace can help explain one authorized staging failure while a count of successes by region remains valuable for longer-term reporting. Before applying a retention period, ask which question each field answers and who needs access to it. If the monthly denominator can be reproduced from aggregate events, there may be no operational reason to keep individual request identifiers for the same duration.
A monitoring gap can arise when the component emitting metrics fails along with the task being monitored. If the worker reports only successful completion, terminated jobs leave silence. Pair the scheduler’s expected-run count with a completion or terminal-outcome count produced where appropriate for the system. A region with ten expected jobs and eight terminal outcomes has two unresolved observations. Recording that uncertainty is more accurate than converting the two missing events into inferred network failures or accidental successes.
Related fieldwork
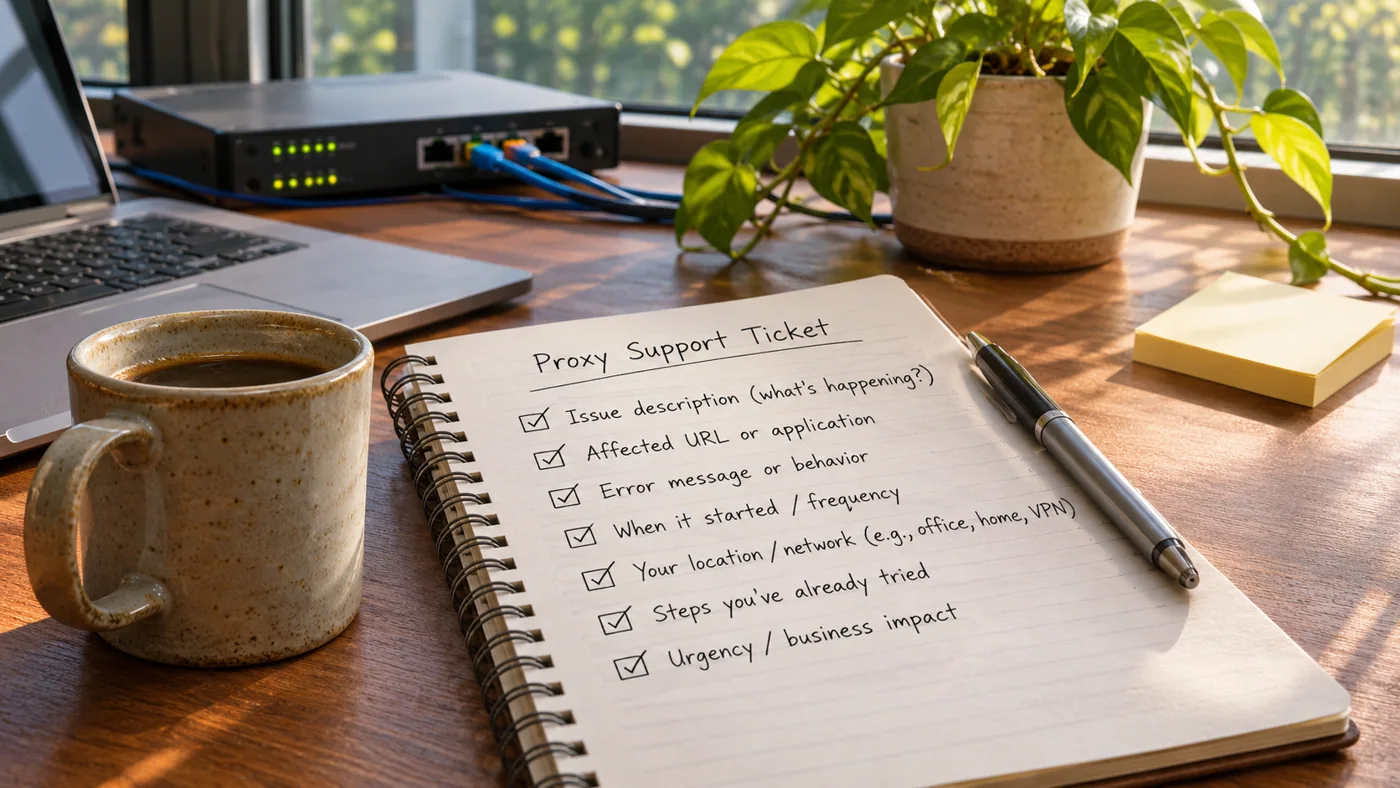
A monitoring design earns its keep when an on-call engineer can classify a real missed deadline or wrong revision using the approved minimal fields. Exercise the diagnostic path on synthetic data first. Regional status page publication supplies a versioned status-page fixture. What to include in a proxy support ticket converts the smallest useful observation into a practical support record. Technical references include OpenTelemetry observability primer. Check XtremeProxy location coverage.
Frequently asked questions
How can we correlate a problem without logging the customer's payload?
Use a scoped synthetic run identifier shared with the first-party service where supported. Keep access and retention rules explicit. Capture only the minimum additional detail needed to resolve the incident through the team's approved process.