Retry budgets for authorized proxy traffic
Budget authorized retries, record first-attempt success and compare recovery cost without repeating side effects at a partner service.
Decide which requests can safely run again
A failed read of an owned status page has different consequences from a timed-out request that created a test reservation. When the origin may have completed a change before the client saw a response, repeating it can create duplicate work. Consult the application's rules for idempotency and the destination owner's acceptable request budget before enabling automated retries.
Limit the extra work
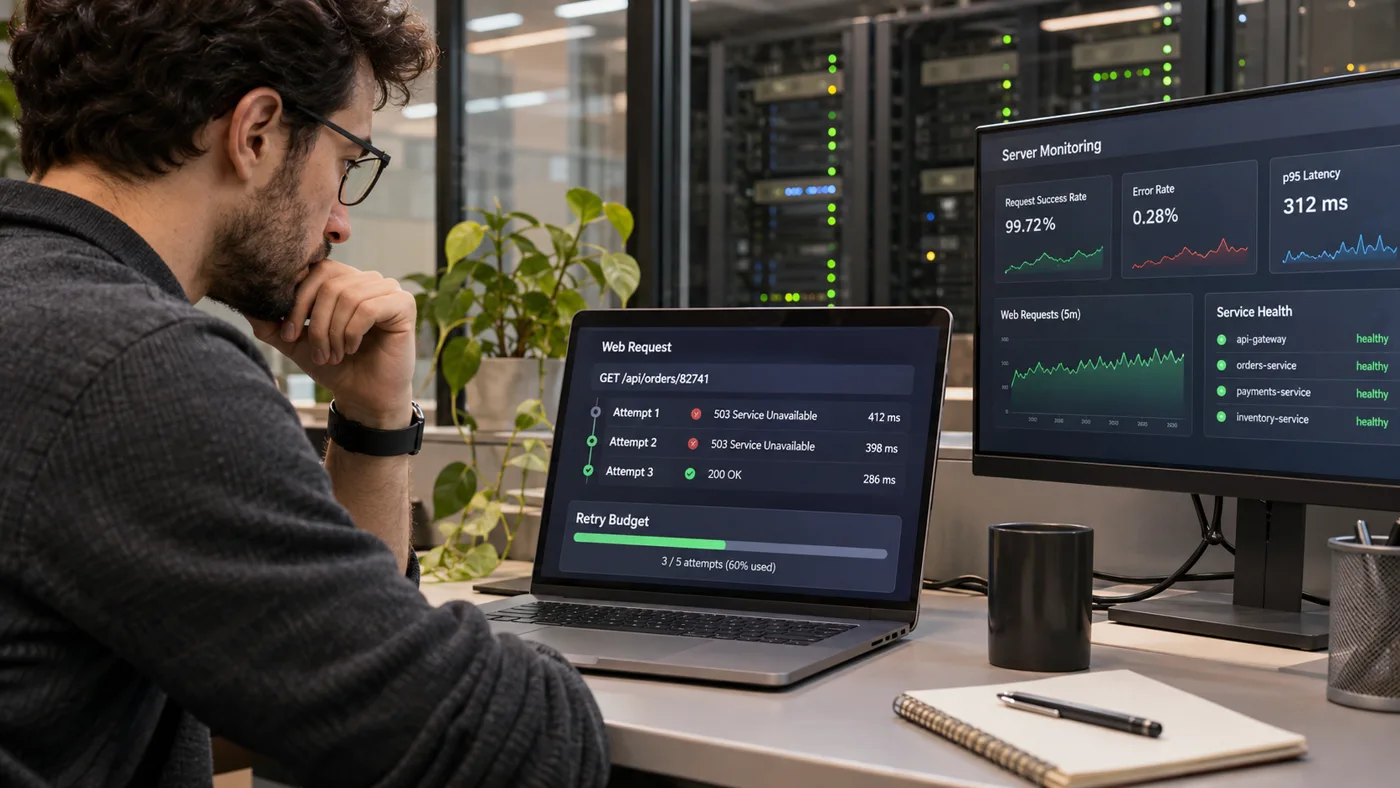
Set a small retry budget that fits the reporting deadline and the destination's approved capacity. Respect explicit instructions from the destination, including any applicable retry time. A recurring permission denial calls for checking authorization. Treat it as a separate outcome in the report. Blind repetition adds load and makes the original problem harder to diagnose.
If 95 items succeed immediately and five recover on a second attempt, report 95 first-attempt successes and 100 eventual deliveries. The distinction matters to a customer whose report is only valuable before a fixed deadline. AWS Well-Architected guidance on retry limits.
Show the first-attempt result
A batch can finish successfully after retries while consuming more bandwidth and taking longer than expected. Track first-attempt success, recovered observations and permanently incomplete work separately. An XtremeProxy evaluation can then compare a route that usually works on the first attempt with one that needs more recovery. Include retry traffic in cost estimates whenever the billing agreement counts those bytes.
Ten recoveries hide a heavy retry bill
In a fictional batch of 100 read-only fixture checks, twenty first attempts time out. Ten recover on one authorized retry and ten remain incomplete. There are 120 attempts and 90 eventual successes. The first-attempt success fraction is 80 percent, and the eventual fraction is 90 percent. Keep both measures in the report. For an operation that creates a record, a lost response can leave the write outcome unknown and demands reconciliation before any repeat.
Treat destination feedback as a constraint
When a service publishes retry guidance or signals a temporary limit, let that constrain the retry budget together with the job deadline and authorization. Count retry attempts across layers. A library and job scheduler can both retry the same failure and create more traffic than either configuration appears to allow.
Retry budgets can be exhausted by duplicate in-flight attempts. If a scheduler times out before the underlying read actually stops, the replacement can overlap the original. In an owned fixture, retain a stable job identifier and distinct attempt identifiers so the owner can see concurrent attempts and account for their traffic.
Count retries at the job boundary
A scheduler permits one repeat, and the client library independently permits one repeat per invocation. A logical job could therefore produce four underlying attempts. Check the layers that actually retry and count physical attempts as well as logical jobs. Applying the agreed total budget at one known boundary makes both performance and usage reports easier to reconcile.
A high eventual success rate can hide poor recovery efficiency. Compare two trial policies that each recover five jobs. One consumes six extra attempts and the other consumes thirty. With the same successful-job count, the latter places considerably more load on the permitted fixture. Report recoveries per additional attempt alongside eventual success and elapsed time. For a workload governed by a destination limit, a small improvement in eventual success may not justify the extra requests needed to obtain it.
Apply the budget at the level that protects the shared service. Fifty individually compliant workers may each schedule two retries after a batch-wide failure, producing a hundred extra attempts in a short window. The application owner can set a shared ceiling for the batch and record which jobs exhausted it. This changes how the team interprets incomplete jobs during an incident: some may never have retried because the budget did its job, while others consumed a retry and still failed.
Related fieldwork
For operations, show both recovered jobs and the extra attempts that recovery consumed. For a business write, describe how the application establishes whether an earlier attempt already completed. Webhook callback staging validation offers a synthetic callback suitable for a controlled acknowledgment test. Right-sizing timeouts in a proxy-backed reporting job bounds the time available for repeats before the report itself becomes late. Technical references include RFC 9110, HTTP semantics. Compare XtremeProxy network types.
Frequently asked questions
Should every failed response be retried automatically?
Classify the operation and failure first. A transient read can have a bounded retry policy. A permission failure or uncertain write can require a different action. Respect documented destination limits and any retry guidance the service returns.