How many samples make a regional proxy benchmark useful?
Choose useful benchmark samples across time, regions and routes, then report missing observations and limitations alongside speed results.
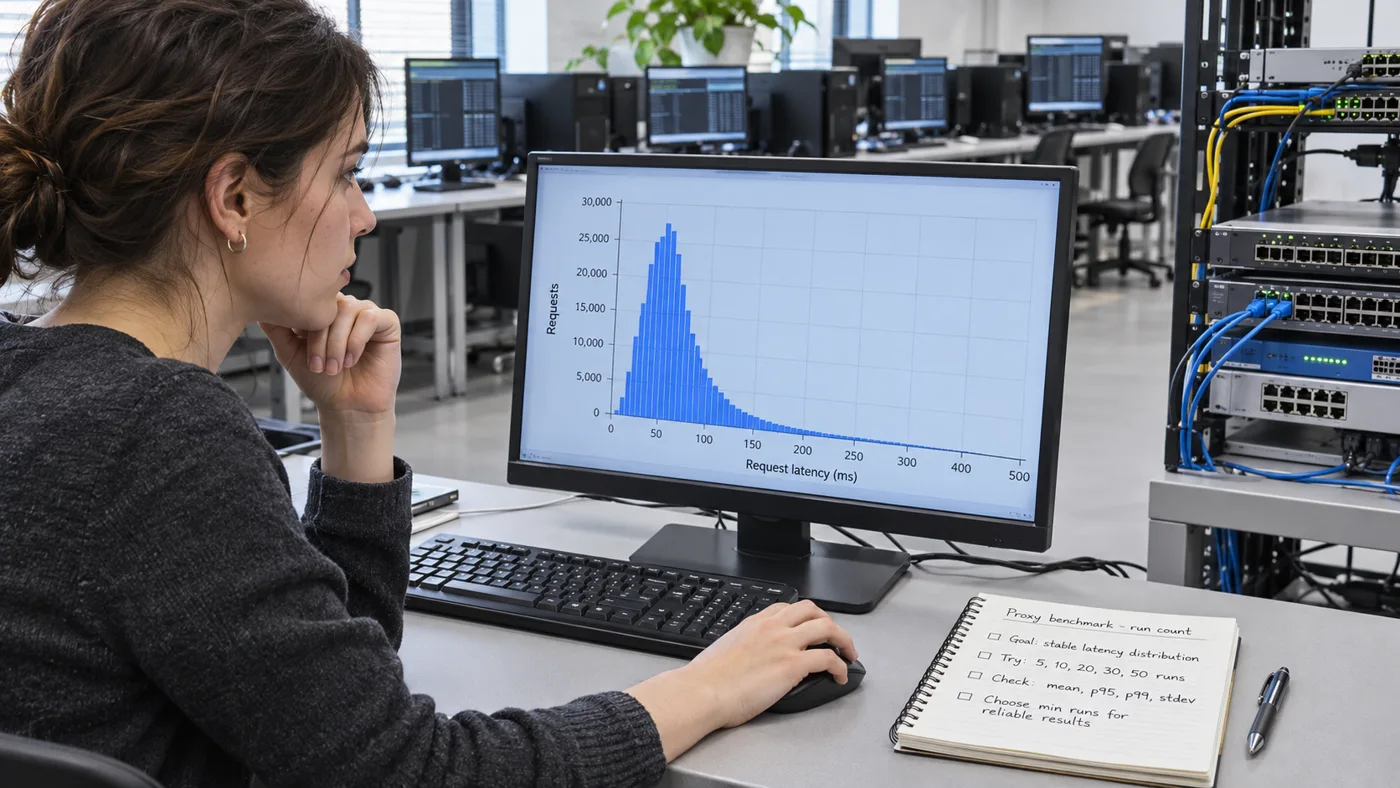
Design the sample around the claim
Five successful requests from a single office can demonstrate that a connection works. They provide weak evidence for a claim about month-long quality across several countries. Before gathering timings, decide what question you need to answer. A trial that selects between two regions needs a different sampling plan from a trial that asks whether one business process survives peak traffic.
Spread observations across plausible conditions
Keep the workload modest and authorized. Distribute requests over relevant local business hours and across the runner locations your customers actually use. Note whenever repeated requests share an exit, session or cached asset. These repetitions can be useful measurements, but they do not give the same evidence as independent routes or independently timed sessions.
Two trials that each contain 100 requests can offer different evidence. One might sample the same warm session for a minute, while the other spans ten business days and several independent deployments. Google SRE on service level objectives.
Report the uncertainty plainly
Show observation counts, failures, measurement dates and the range of tested conditions. If one cell contains only three runs, label it as an initial check. Resist turning it into a fine-grained ranking between two nearly equal services. In an XtremeProxy pilot, prioritize enough evidence for the particular purchase decision. An extra day of measurements at the customer's busiest hour may be worth more than another hundred tests taken immediately after the first.
An empty failure column in a tiny sample
A pilot runs ten authorized checks during a quiet hour and observes no failures. Report ten successes in those conditions. One missed observation in the next ten would move the pooled success fraction to 19 of 20. This illustrates how fragile a small estimate can be. Spread a proportionate sample across meaningful hours, releases and route conditions, then compare it with the claim the buyer actually wants to make. Persistent uncertainty calls for a qualified conclusion.
Choose a sample plan with named conditions
An evenly spaced sample can miss a brief but important release window. A burst of many requests can measure one event repeatedly while ignoring normal variation. Select windows that match the decision and respect the destination's approved load. Include incomplete attempts and observations that could not be scheduled.
Ten requests sent through one connection can share a temporary congestion event, cache state or edge choice. A large count of correlated observations can exaggerate confidence. Vary observation windows deliberately and present the number of independent runs as well as the total number of requests.
Check the effect of one observation
A small trial records twenty opportunities, and changing one outcome moves its success estimate by five percentage points. A larger sample improves resolution but still needs appropriate time coverage and independent conditions. Show the number of opportunities and the actual failure count next to any percentage. Excess decimal places can suggest precision the design never supplied.
Sampling at an exact interval can repeatedly miss a periodic issue. A worker running only at the top of each hour will never observe a short disruption confined to a scheduled half-hour maintenance action. Select observation times that cover the business hours and relevant maintenance windows within the approved request volume. Include the sampling schedule in the report. A hundred successful readings from one narrow phase of a repeating cycle answer a narrower question than a hundred readings distributed across the cycle.
Write down a stopping rule before reading the results. Ending a pilot after the first run of ten successes produces a flattering report even when earlier runs contained misses. A defensible small pilot can instead define its observation dates and conditions first, include every eligible attempt during those windows, and disclose missing observations. A later extension can be reported as a new sampling period. This keeps the decision to collect more data separate from the temptation to stop on a favorable result.
Related fieldwork
State the outcome as a claim the measurement can bear. A few quiet-hour successes support a pilot observation. Broad decisions need suitably varied, authorized opportunities and an explicit treatment of missing data. Geographic release canaries shows how to scale a small regional trial. Measuring proxy speed with median and p95 latency explains how to summarize the latency distribution once the sample is defined. Technical references include Google SRE Workbook on implementing SLOs. Compare XtremeProxy network types.
Frequently asked questions
Does a larger sample fix a biased test window?
More observations from the same quiet interval can estimate that interval more precisely. They cannot establish what happens during other relevant conditions. Design coverage of those conditions before increasing request volume.